Mastering Data Processing for Startup Growth and Smart Decisions
In today’s fast-moving world of 2026, founders, investors, and business operators are swimming in more information than ever before. But here’s the thing: having lots of data does not always mean having clear answers. Actually, it often means dealing with noisy signals and fragmented data. This makes it really hard to make smart choices.
When data is messy or spread out, it’s tough to see what’s truly happening. This can lead to big problems. Bad decisions based on poor data can cost startups a lot of money and make investors put their money in the wrong places. Think about it: if a company can’t properly use its data, it might miss important chances to grow or even misunderstand its customers. This shows why good data processing is so important.
This guide is here to help. It will map out the basic building blocks of data science. We will look at how skills like data curation, which means cleaning and organizing data, help turn messy information into useful insights. Understanding "data literacy" is also key, helping everyone from a founder to a junior data analyst to better understand and talk about what the data means. Learning these basics can even help you know what kind of data analyst interview questions to ask to find the right talent. Many university courses, for example, teach key math and statistics methods needed for applied data science, showing just how fundamental these skills are DATA 202 – Mathematics for Applied Data Science.
We’ll give you practical checkpoints that founders and investors can start using right away. This way, you can move from just having data to truly understanding it and making decisions that drive success. Getting better at managing information, right from the start, is truly mastering mastering data ingestion for startup smart decisions and growth.
To stay on top of the latest advancements in how data and AI are shaping the future, consider exploring more resources.
Get clear daily AI updates from The AI Newsletter Worth Reading.
The journey from messy data to clear decisions starts with understanding some basic math ideas.
These ideas are like the tools in a builder’s toolbox for anyone working with data. For founders and investors in 2026, grasping these core concepts is key to smart data processing. Many top programs agree that math skills are super important for data science, covering things like probability, descriptive statistics, and linear algebra for applied data science work Mathematical and Statistical Foundations (MSF) – ACM.
Statistics: Making Sense of Startup Numbers
Statistics helps us understand big groups of numbers. Imagine you’re looking at how many users sign up each day.
- Distributions: This concept helps us see how our data spreads out. Are most users signing up in the morning, or is it even throughout the day? Knowing the distribution helps you see patterns. For a startup, understanding the distribution of customer ages or how much money they spend helps you tailor your products better.
- Hypothesis Testing: This is like playing a "what if" game with your data. Let’s say you try a new marketing campaign. You might guess (form a hypothesis) that the new campaign will bring in more customers. Hypothesis testing uses statistics to check if your guess is likely true or just a coincidence. This helps you know if your changes are actually working.
- Confidence Intervals: When you look at a metric, like the average time a user spends on your website, you can’t be 100% sure of the exact number for all users. A confidence interval gives you a range where the true average probably sits. For example, you might be 95% sure that the average user spends between 3 and 5 minutes on your site. This gives you a clear picture of how reliable your metrics are.
These statistical ideas help founders and investors truly interpret important startup metrics and make sense of their business performance.
Probability: Predicting Future Events
Probability is about understanding chances. It helps us predict how likely certain events are to happen. For example, what’s the chance a new customer will make a second purchase? Or what’s the likelihood your product will succeed in a new market? Basic probability helps us weigh risks and opportunities. This foundation is a key part of "mathematical foundations" for data science degrees, alongside linear algebra and statistics Syllabus – Module 1: Mathematical Foundation.
Linear Algebra: The Structure Behind the Data
Linear algebra might sound fancy, but it’s really about working with numbers in organized boxes called "matrices" and "vectors." Think of a spreadsheet where each row is a customer and each column is a feature of that customer (like age, location, how much they bought). That’s a matrix!
Linear algebra helps with many parts of data processing and building smart computer models.
- Organizing Data: It gives us a simple way to arrange and work with large sets of data, making tasks like data curation much easier.
- Modeling: When you build models to predict things (like future sales or customer behavior), these models often rely on linear algebra to crunch the numbers quickly. It’s the backbone for many machine learning tools that a junior data analyst would use.
By understanding these core concepts, you build a stronger base for becoming truly data literate. This way, you can ask better questions, understand answers more deeply, and even know what kinds of skills to look for when hiring a new data analyst.
After you understand the basic math behind data, the next big step is actually handling the data itself. This is where data processing comes in. It’s like building a factory for your numbers, making sure they are collected, cleaned, and ready to be used.
For any startup, doing this well is super important for smart choices and growth in 2026.
The Data Processing Lifecycle: From Start to Finish
Data processing generally follows a few key steps:
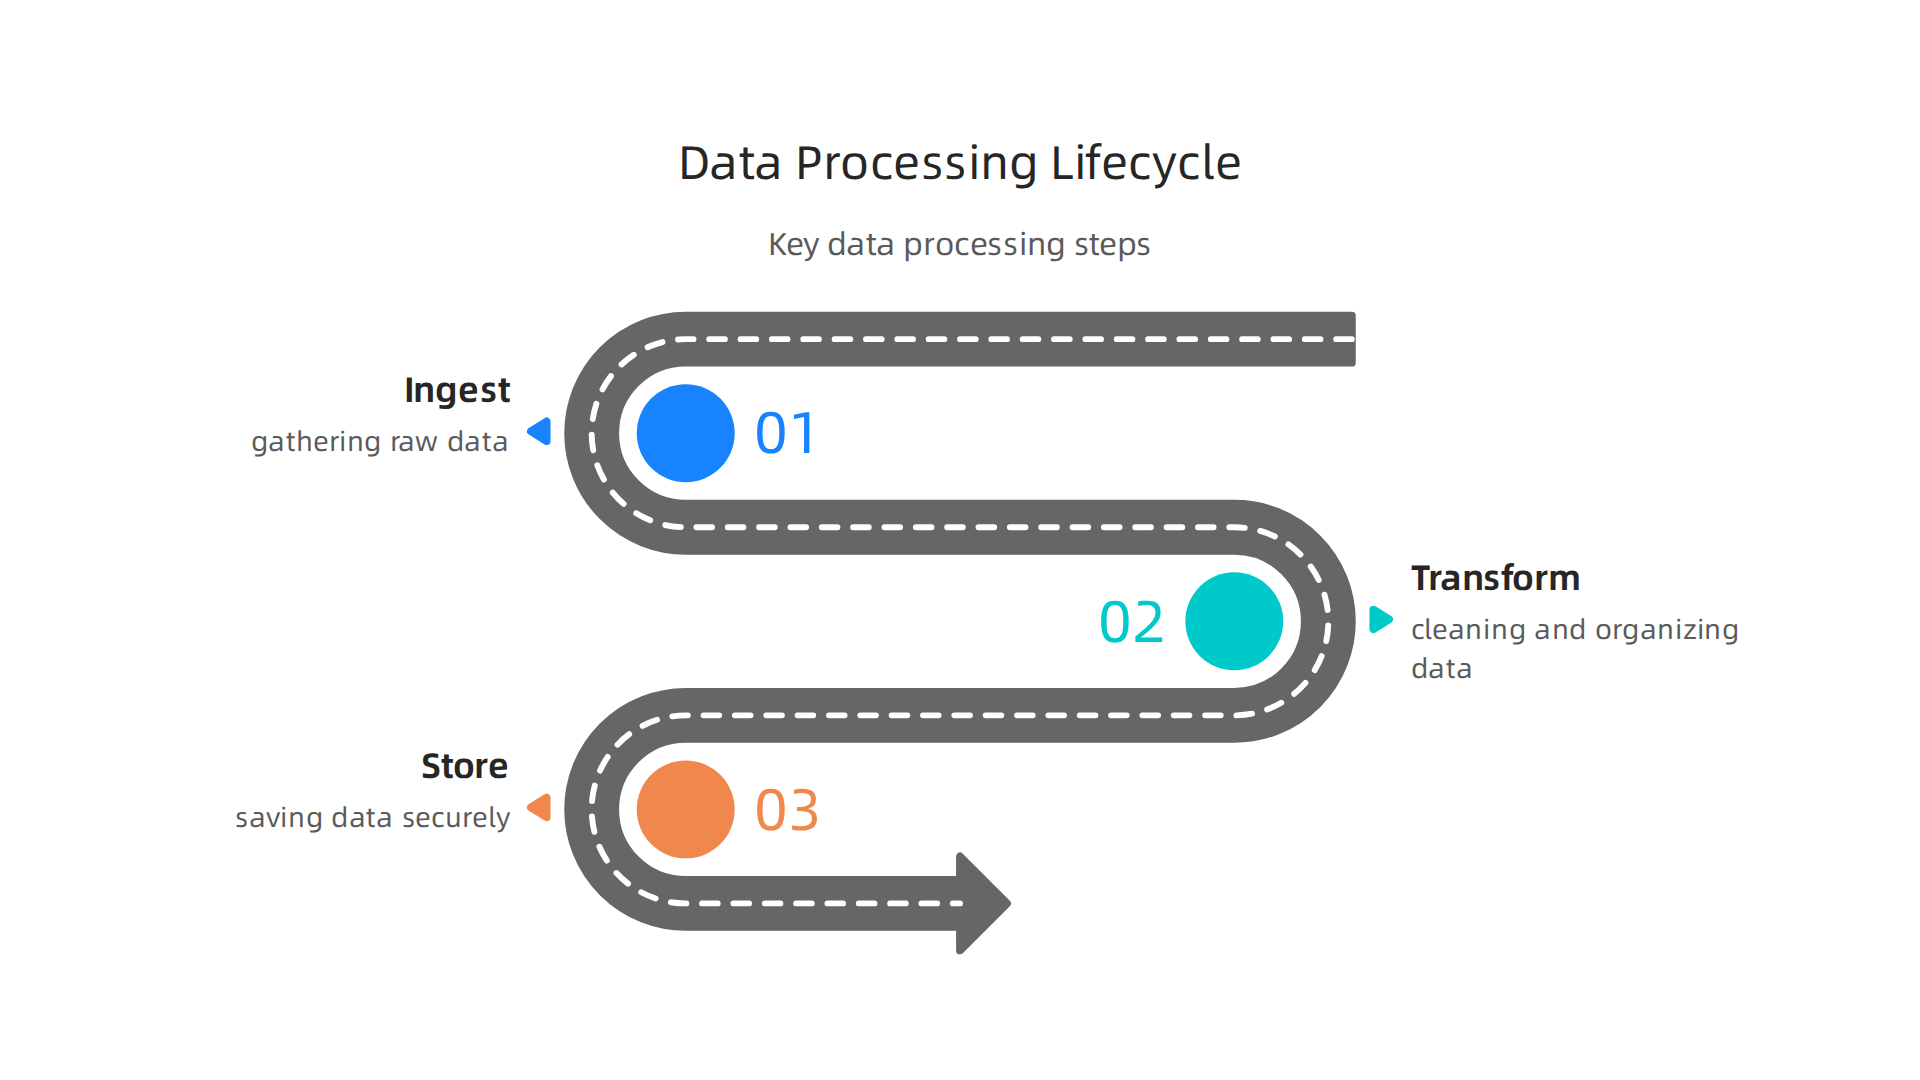
- Ingest (Collecting): This is about gathering raw data from different places. Think of it like collecting all the ingredients for a recipe. Data can come from your website, app, customer surveys, or even social media. Learning how to effectively pull in all this information is key to making good decisions. You can find more tips on mastering data ingestion for smart decisions.
- Transform (Changing): Once collected, data often isn’t perfect. It might have errors, be in the wrong format, or have missing pieces. This step, often called data curation, involves cleaning, organizing, and changing the data so it’s ready for analysis. It’s like chopping veggies and mixing sauces before cooking. Without this step, your analysis might be wrong.
- Store (Saving): After being collected and transformed, the data needs a safe place to live. This could be a database or a data warehouse, making it easy to access when you need it. This entire flow of collecting, changing, and storing data is called a data pipeline. You can learn more about how to build your modern data pipeline for startup success.
Batch vs. Streaming: Choosing Your Data Flow
When it comes to moving and processing data, you mainly have two ways to do it:
- Batch Processing: This is like sending out emails once a day. You gather all the data over a period (like an hour, a day, or a week) and then process it all at once. This method is often cheaper and simpler for large amounts of data that don’t need to be acted on right away. It’s great for things like monthly reports or training machine learning models that update less often.
- Streaming Processing: Imagine getting messages on your phone right as they happen. Streaming processing works similarly, dealing with data as it arrives, piece by piece. This means you get insights almost instantly, which is perfect for fraud detection, real-time alerts, or making sure your website shows the right things to users right now. Tools like Apache Kafka are often used for this kind of work, allowing for continuous transformation of data.
Choosing between these depends on how fresh your data needs to be. If waiting a few hours or a day is fine, batch processing is usually enough and costs less. But if you need to make decisions in seconds, then streaming is the way to go, even if it’s more complex and expensive to set up. Knowing the difference helps you pick the right tools and approach for your startup’s needs Streaming ETL vs Batch ETL: Which Approach Is Right for ….
Key Checkpoints for Startups
For startups, thinking about data processing also means keeping these things in mind:
- Data Provenance: This means knowing exactly where your data came from and how it changed along the way. It’s like tracking the source of every ingredient in your recipe. This helps you trust your data and fix problems if they come up.
- Schema Management: This is about keeping your data organized and making sure everything fits together. As your startup grows, your data will change, and you need a clear plan for how new data will be structured.
- Cost Control: Data processing can get expensive, especially with streaming data. Startups need to be smart about how much they spend on storing and processing data. Always ask if the speed or complexity is truly worth the cost for your business goals.
Understanding these steps and choices in data processing helps you build a strong foundation for your startup. It also means you’ll know what to look for when hiring a junior data analyst or someone to manage your data systems.
Want to stay on top of the latest tech trends shaping data and AI?
The AI Newsletter Worth Reading
Get clear daily AI updates from The Deep View Newsletter.
3) Data Cleaning and Validation: Creating Reliable Inputs
After understanding how to collect and move your data through the data processing steps, there’s another very important part: making sure that data is clean and correct. Think of it like cooking with fresh, good ingredients. If your ingredients are bad, your meal won’t taste good, no matter how skilled the chef is. The same goes for data. If your data is messy or wrong, any decisions you make from it will also be wrong. This is where data cleaning and validation come in.
Common Data Problems and How to Fix Them
Data often comes with problems. It’s rare for raw data to be perfect. Here are some common issues:
- Missing Pieces: Sometimes, important information is just not there. Imagine a customer survey where people skip the age question. If you need age for your analysis, this missing data is a problem. You might have to guess based on other info, or just leave those entries out.
- Duplicate Entries: You might have the same customer or sale listed twice. This can mess up your totals and make things look bigger than they are. Finding and removing these duplicates is key.
- Inconsistent Types or Formats: Data might be entered differently. One person types "NY" for New York, another types "New York," and another uses "N.Y.". Or dates might be in different styles. This makes it hard to group things together. Making everything uniform, like a proper data curation effort, helps a lot.
- Outdated Information: Data can get old quickly. An old customer address or phone number isn’t helpful anymore.
For startups, having clean data is super important for product and investment metrics. It ensures that when you report growth, customer numbers, or funding progress, those numbers are truly reliable. You can find more helpful ways to fix these issues in guides like Data Quality in 2026: Metrics, KPIs, Scorecards, and Fixes.
Building Strong Data Validation
Data validation is the process of checking your data to make sure it meets certain rules and quality standards. It’s like having a quality control team for your numbers. Instead of fixing problems after they appear, validation tries to stop them from happening in the first place or catches them very early.
Different types of checks can be done:
- Type Checks: Making sure a number field only has numbers, or a date field only has dates.
- Range Checks: Ensuring values fall within an expected range (e.g., age cannot be 200).
- Completeness Checks: Checking that important fields are never left empty.
- Consistency Checks: Making sure related pieces of data don’t contradict each other (e.g., a customer’s order date isn’t before their sign-up date).
To make this work well, you can use automated tools and build validation into your data systems. For example, some tools allow you to define rules that check your data as it flows in. These are important techniques for anyone wanting to master data validation.
Validation Pipelines and Automated Tests
For startups, it’s not enough to just clean data once. Data is always changing, so you need a way to keep it clean over time. This is where validation pipelines and automated tests come in.
Imagine a pipeline where every new piece of data goes through a series of checks before it’s used. If data fails a check, it’s flagged and stopped, preventing bad data from entering your main system. This process helps catch issues early. These checks can also be part of what’s called Continuous Integration (CI), which means they run automatically every time new code or data changes are made. This helps catch any new problems or "regressions" in data quality that might pop up.
Automating these checks is a best practice for Data Quality Checks in 2026. This setup means your team, especially any junior data analyst you might hire, can trust the data they’re working with. This ensures everyone has good data literacy, understanding that the numbers they see are reliable. Investing in tools that help with this automation is a smart move for any startup aiming for consistent growth and accurate reporting. After all, reliable data is the backbone of clear data dashboards that fuel startup success.
After making sure your data is clean and correct, the next step in data processing is to turn that raw data into something truly useful. This is called feature engineering and selection. Think of it like a detective finding clues. Raw data is just a pile of facts, but features are the specific, important clues that help you solve a mystery or predict what will happen next. For startups, this means turning user actions or product details into "signals" that can predict things like customer churn, future sales, or which users will love a new feature.
Creating Smart Features from Your Data
Feature engineering is all about creating new, meaningful variables (features) from your existing data. It’s how you make the data tell a story.
Here are some common ways to create powerful features, especially from product data:
- Time-Series Features: This looks at how things change over time. For example, instead of just seeing one purchase, you might look at how many purchases a customer made in the last week, month, or year. Or how long they spent on your app each day. These time-based patterns are great signals.
- Aggregate Features: These combine many pieces of data into a single, summary number. Imagine figuring out the total amount a customer has spent with you, or the average number of times they’ve used a certain feature. These summaries can highlight important trends.
- Behavioral Counts: This involves counting specific actions users take. How many times did a user click a button, log in, or share something? These counts show engagement and can help predict future actions.
To manage all these useful features, many companies use what are called "feature stores." These are like organized libraries where all your created features are kept ready to be used by different data models. This helps keep your data processing consistent and makes it easier for everyone on your team, even a junior data analyst, to access reliable information.
Choosing the Best Features
Once you have many potential features, you might have too much information. This can make models slow, hard to understand, and sometimes less accurate. That’s where feature selection comes in. It’s about picking only the most important and useful features for your models, like choosing the best tools from a big toolbox for a specific job.
This process is sometimes called dimensionality reduction because it reduces the number of "dimensions" or variables your model has to work with. Choosing the right features helps your models stay strong and easy to explain, which is key for making good decisions.
Some ways to do this include:
- Filter Methods: These methods check each feature on its own to see how well it relates to what you want to predict. For instance, you might see if a feature like "total time spent" strongly correlates with whether a customer buys something.
- Wrapper Methods: These are more involved. They try out different combinations of features with your actual prediction model to see which set works best. It’s like building several small models to find the ideal group of clues that gives the best results.
By doing this, you remove features that are not helpful or that repeat information, making your models more robust and easier to interpret. Learning about Dimensionality Reduction and Feature Engineering is a key skill for working with data effectively. This thoughtful approach to data processing ensures that your data science efforts lead to clear, actionable insights.
Staying informed about the latest in AI and data can give your startup a real edge.
Get clear daily AI updates from The AI Newsletter Worth Reading.
After getting your data ready through data processing steps like feature engineering and selection, the next big step is to pick the right model to make predictions or find patterns. This is called model selection. It’s like choosing the best tool for the job.
For startups, this choice depends a lot on your business needs and any rules you have to follow.
Choosing the Right Models for Your Startup
One key decision is between models that are "interpretable" and those that are "black-box."
- Interpretable models are easy to understand. You can see how they make their decisions. For example, a simple model might say, "If a customer hasn’t logged in for 30 days AND their last purchase was over $100, they are likely to leave." You can clearly see why it made that prediction. These models are great when you need to explain why something happened, especially in areas with strict rules like finance or healthcare. Being able to explain your AI’s decisions is becoming more important for driving ethical AI and ensuring real-world impact.
- Black-box models, on the other hand, are very complex. They often give highly accurate predictions, but it’s hard to understand how they got to that answer. Think of advanced AI systems that recognize faces or translate languages. They work incredibly well, but figuring out the exact steps they took is very difficult. These models are usually chosen when top performance is the most important thing, and explaining every single decision isn’t critical.
Many people used to think you had to pick between a model that was accurate OR one that was easy to understand. This was called the "accuracy-interpretability trade-off." However, newer research in 2026 shows that for some types of data, you can often have both high accuracy and good interpretability, challenging this old idea. Studies have explored how model behavior is influenced by meta-features and suggest there isn’t always a strict trade-off between predictive performance and model interpretability Challenging the Performance-Interpretability Trade-Off. The choice often comes down to the specific task and the risks involved. If a wrong prediction could cause serious harm or legal trouble, an interpretable model is usually the safer bet. Understanding the math behind these models, including probability and statistics for data science, is fundamental for a data analyst.
Evaluating Your Model’s Performance
Once you’ve chosen and built your model, you need to check how well it works. This is called model evaluation. It’s not just about getting a high "accuracy" score. Accuracy simply tells you how many times the model got the right answer. But for real business situations, you often need to look deeper.
Here are some other important ways to evaluate your models:
- Calibration: This checks how confident your model is in its predictions. If a model says it’s 80% sure a customer will buy something, and that customer actually buys it 80% of the time when the model makes that prediction, then the model is well-calibrated. This is super important when you’re making decisions based on the model’s certainty, like deciding how much to invest in an ad campaign for a specific user.
- Business-aligned KPIs (Key Performance Indicators): Instead of just technical scores, you should measure how your model helps your business goals. For example, if your goal is to reduce customer churn, you might track how many customers your model correctly flagged as "at risk" and how many of those you were able to save. This means connecting the model’s output directly to your company’s mastering AI and data business strategy for 2026 growth. Visualizing these metrics through data dashboards fuel startup growth and help attract investors.
- Validation for time-based data: Many startups work with data that changes over time, like daily website visits or weekly sales. When testing models with this kind of data, you need special methods. You can’t just mix up all your data. Instead, you train your model on older data and test it on newer data to see if it can predict the future. This helps you understand if your model will keep working well as time goes on. Learning how to choose the right data analytics courses can help you develop these skills.
Effective model selection and thorough evaluation are crucial parts of the overall data processing pipeline. They make sure your AI and machine learning efforts actually solve real problems and lead to better business outcomes. Knowing how to evaluate AI platforms for your startup in 2026 can make a big difference.
6) MLOps & production: serving, monitoring, and reproducibility
After picking the best model and checking how well it works, the next big step is to put it to use. This is where MLOps comes in. MLOps is about making sure your machine learning models work well in the real world, stay healthy, and can be updated easily. For startups, this means deciding how your model will actually make predictions for your customers or business. This final stage is a crucial part of your entire data processing pipeline.
Deployment Options for Your Models
When you "deploy" a model, you’re making it available to do its job. There are different ways to do this, each with its own pros and cons for a startup:
- Batch Scoring: Imagine you have a lot of data that comes in every night, like all the sales from yesterday. You can run your model on this data all at once to make predictions. This is called batch scoring. It’s good for tasks that don’t need instant answers, like creating daily reports or training new models. Batch processing handles data in "batches" at scheduled intervals, such as hourly or daily. This method is often the most cost-efficient choice for tasks like reporting and historical analysis where near-instant results are not required. Batch pipelines process data on a fixed schedule and are very economical per row of data processed.
- Online Inference (Streaming): If your startup needs instant answers, like detecting fraud as soon as a transaction happens or giving real-time product recommendations, you need online inference. This means your model is always ready to make a prediction for one piece of data at a time, as it arrives. It’s also called streaming processing because it handles data continuously. This approach provides very low latency, meaning predictions happen almost instantly, which is perfect for decisions that depend on fresh data, such as fraud detection or real-time personalization. Streaming ETL is the right choice when decisions depend on fresh data.
- Serverless Deployment: For startups that want to focus purely on their model and not worry about managing servers, serverless options are a great fit. With serverless, your model code runs only when a prediction is needed, and you only pay for the exact time it runs. This scales up and down automatically, saving you time and money on server upkeep. This can be part of building your modern data pipeline for startup success.
Choosing the right way to deploy depends on how quickly you need predictions and how much data processing you’re doing.
Monitoring Models in Production
Once your model is live, your job isn’t over. You need to keep a close eye on it to make sure it’s still working correctly.
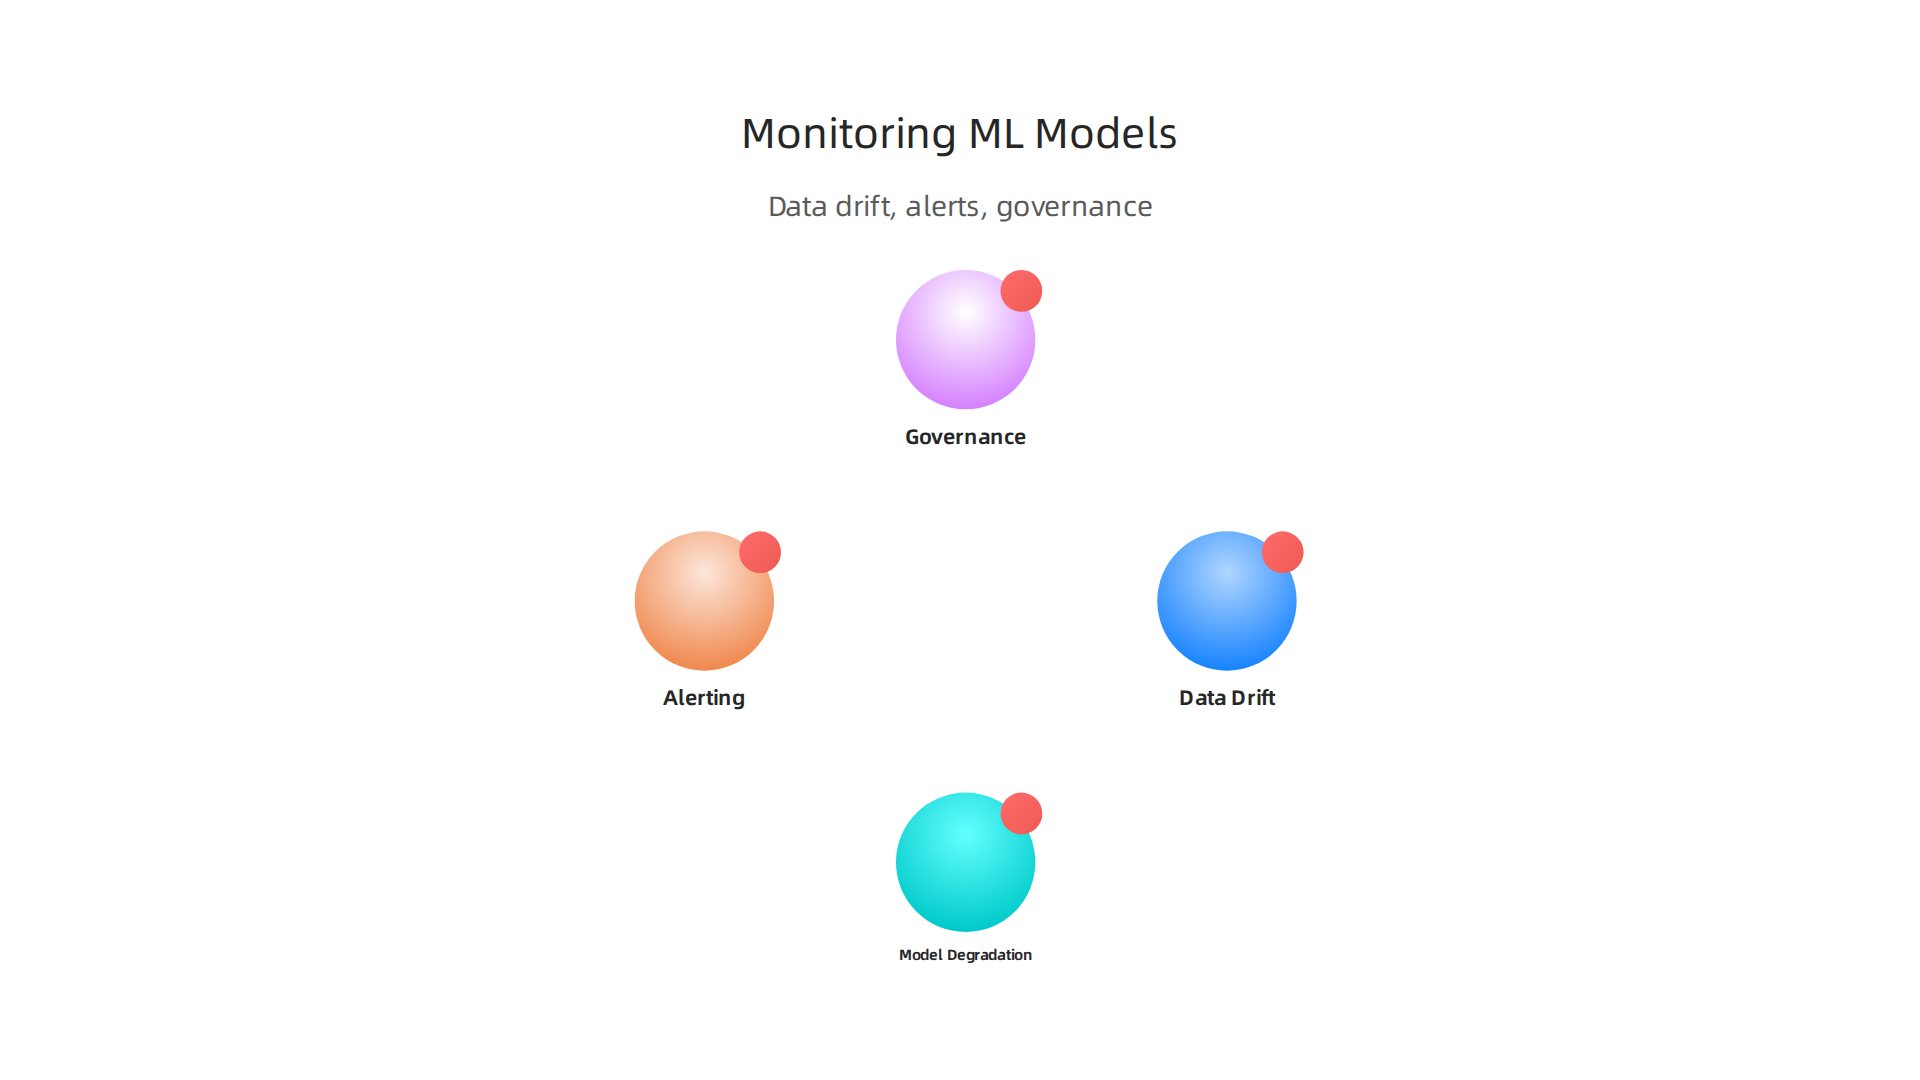
This is a crucial part of MLOps.
- Data Drift: What if the real-world data your model sees starts to change from the data it was trained on? For example, if your model was trained on customer behavior from 2024, but customer habits have changed a lot by 2026. This is called data drift. If this happens, your model’s predictions might become less accurate. It’s important to set up data drift detection to catch these changes early. Monitoring changes in input data prevents your model from making bad predictions. You should define the types of drift you care about and their business impact.
- Model Degradation: Sometimes, even without data drift, a model’s performance can drop over time. This is called model degradation. It might start making more mistakes or its confidence in predictions might decrease. Tracking model performance over time, like its accuracy or error rate, is key. You need to watch for any drop in its effectiveness. Automated retraining pipelines can help maintain model accuracy and reliability.
- Alerting: You can’t stare at dashboards all day. Setting up alerts means you get a notification if something goes wrong. For example, if data drift is detected or if the model’s accuracy drops below a certain level. This lets your team fix problems quickly before they cause big issues for your business. You can set up alerts for a prediction accuracy drop or other issues related to model health.
- Governance Checkpoints for Investors: For startups, showing investors that your AI models are fair, transparent, and compliant with rules is very important. This includes having clear rules for how models are developed, deployed, and monitored. Good governance means you can explain your model’s decisions, show that it’s not biased, and prove it’s still performing well. This builds trust and shows responsibility, which matters a lot when attracting new funding or dealing with regulations.
By carefully managing your models after deployment, you make sure your data processing efforts continue to deliver value and help your startup grow.
Get clear daily AI updates from The AI Newsletter Worth Reading.
Summary
This guide walks founders, investors, and operators through the practical foundations of data science needed to turn noisy, fragmented information into reliable decisions. It explains the core math skills—probability, statistics, and linear algebra—that help you interpret metrics and build models, then maps the full data processing lifecycle from ingestion and transformation to storage. The article covers how to choose between batch and streaming flows, how to clean and validate data with automated checks, and how to build useful features that power predictive models. It also explains model selection, evaluation metrics tied to business KPIs, and MLOps tasks for deploying and monitoring models in production. Throughout, the emphasis is on concrete checkpoints—data provenance, schema management, cost control, and governance—so startups can scale data work responsibly and present credible results to investors. After reading, you’ll know which tools and practices to prioritize to improve data quality, make faster decisions, and reduce risk when putting AI into production.